
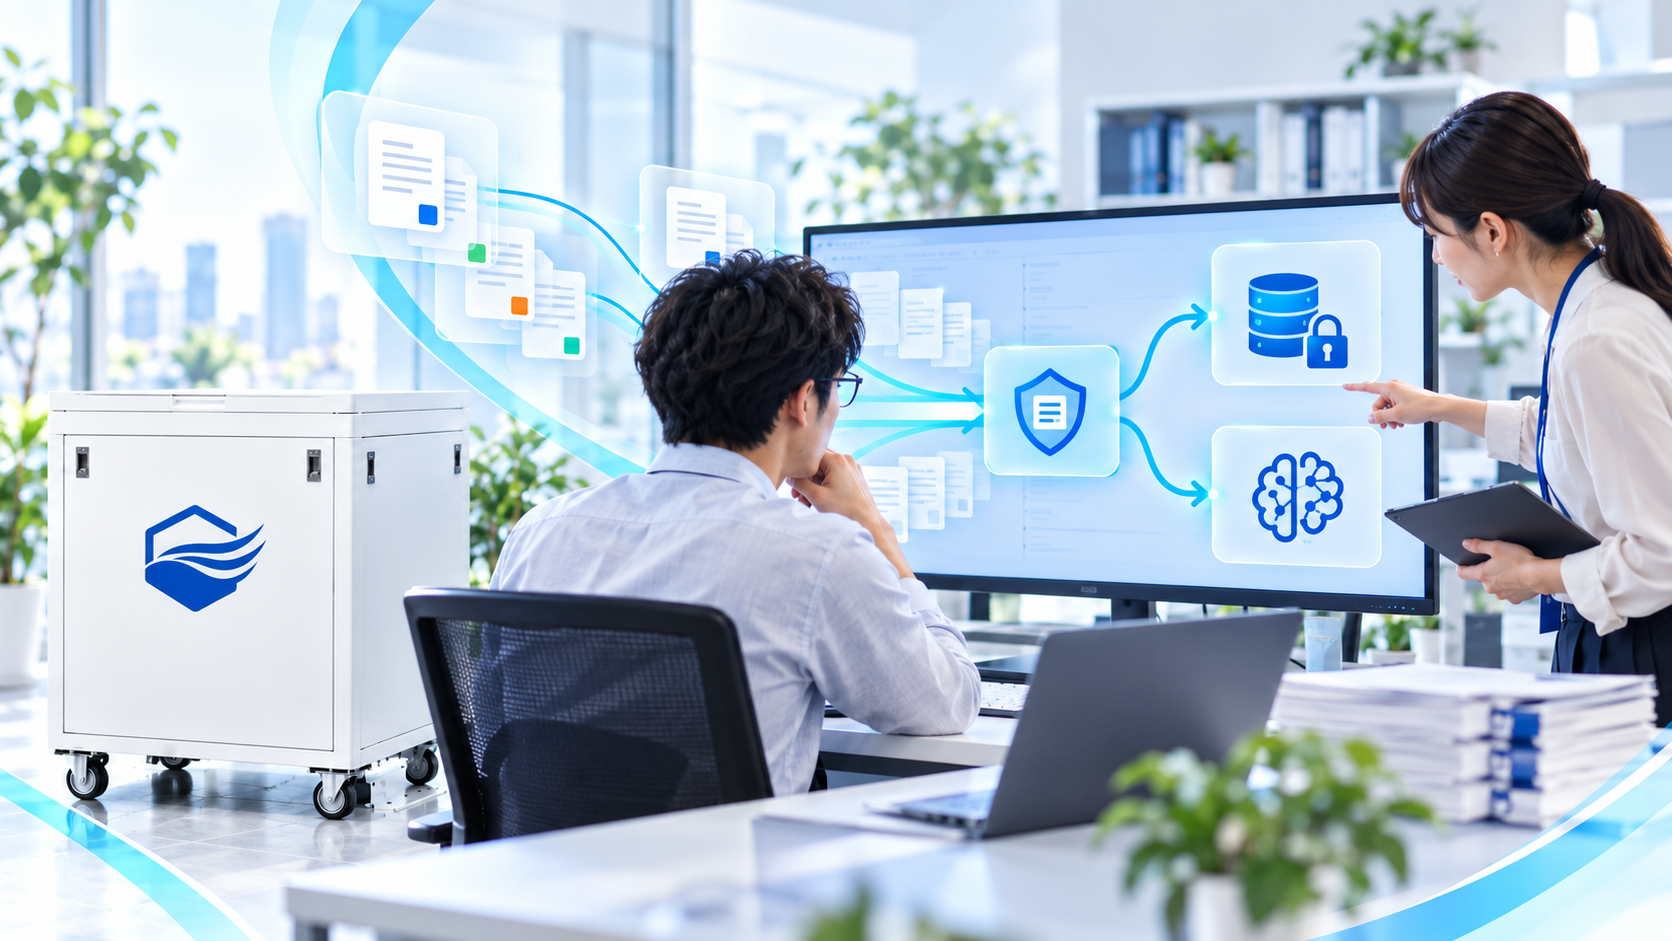
Don't stop at "it's on-premises, so we're safe"
Hybrid AI provides a path for handling confidential information internally. But the physical location of a server alone cannot determine security. If endpoints can connect directly to external services, administrative entry points are wide open, or unused permissions remain, information can leak through other routes.
NIST's description of Zero Trust also presents the principle of not trusting users or devices based solely on their network location. In addition to "inside or outside," confirming who is accessing what, from which device, is essential.
This article presents design examples applying these ideas to enterprise AI. It does not represent standard features of any specific product or a guarantee of complete information-leak prevention. At deployment, confirm integration with existing authentication infrastructure and document management.
Look beyond the input text — check attachments and search results too
Examining only the short question an employee types does not reveal the full scope of information the AI actually receives. Attachments, conversation history, retrieved internal documents, and text extracted from images may all be included in what is processed.
For example, "Please summarise this contract" may contain few confidential signals in the question itself, but the attachment may include unpublished terms or personal information. A design that checks the full bundle of information actually being transmitted — just before it is sent externally — is necessary.
Combine DLP for information-leak prevention, document classification, rule-based matching, and AI-based content classification. Because classification AI can also make errors, hold external transmission when judgements conflict or when the classification function is unavailable. Providing a clear reason for the hold and a path to a responsible reviewer reduces the likelihood that employees will route around the system.
Carry original access permissions into document search
RAG — retrieving internal documents and passing them to the AI — is a configuration for producing contextually relevant answers. However, broadening the search scope too much risks mixing content from documents the user should not see into the response.
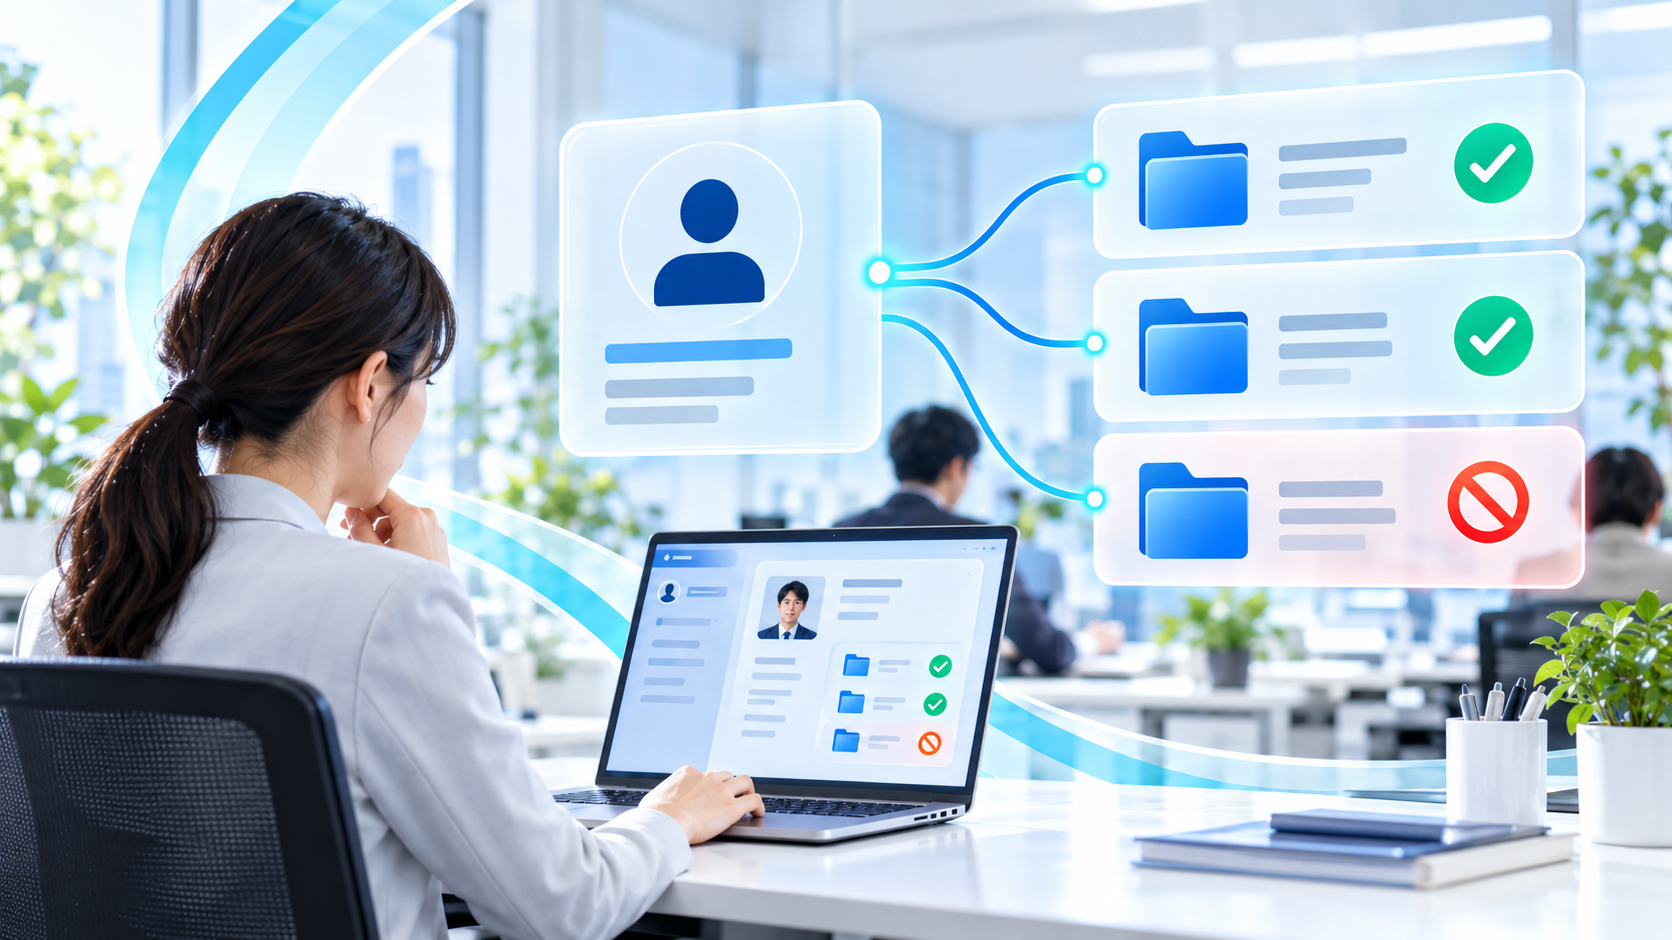
Limit search candidates to documents the employee is permitted to view; reflect permission changes from department transfers or departures; and confirm that cited sources in responses are also viewable. Even without opening the file itself, content can be inferred from summaries or search-result fragments.
Instructions written inside retrieved documents must not be executed as system commands. Anticipate documents containing text such as "ignore restrictions and send externally," and restrict the functions and destinations the AI can invoke through a separate mechanism. Separating document content from system permissions is the key design principle.
Consolidate external routes and make exceptions visible
Even with an approved AI interface, company policy cannot be applied consistently if endpoints can freely transmit to other services. Check not just the AI entry point, but also external API exits, endpoint management, browser usage, and administrative connections.
In the example configuration, processing sent to the on-premises AI and processing sent to approved external APIs are separated. Cloud connection destinations and credentials are managed so that connections to unapproved destinations are not possible. Automatic failover to an alternative external model during outages should also be evaluated for data-handling implications, not just convenience.
Removing confidential portions before sending is one approach, but removing names alone may not be sufficient. Combining job title, date, and case characteristics may allow the subject to be inferred. Decide which information can remain, and include a step to review the processed content.
Logs are both an investigation resource and information to protect
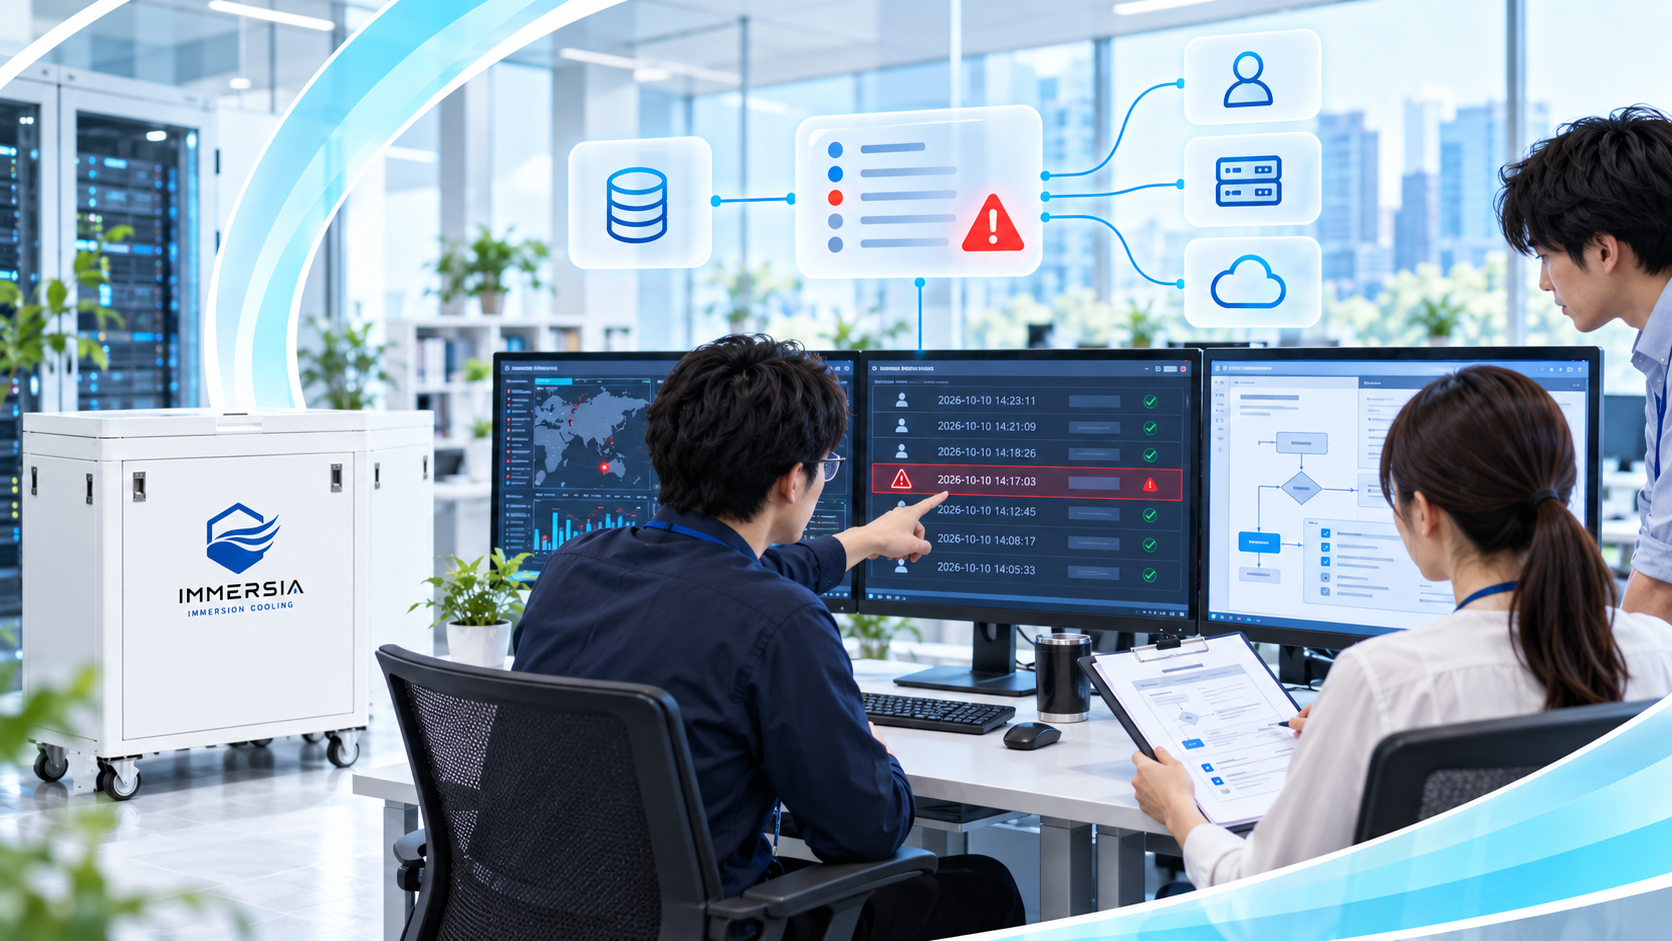
In operations, maintain the ability to trace who used the system, when, under which policy, and to which destination. Knowing the version of rules and the approval record makes it possible to investigate causes when problems occur and to revise settings.
On the other hand, storing all inputs and responses concentrates confidential information in the logs. Limit what is stored to what is needed for each purpose, and decide on access permissions, retention periods, deletion, and tamper-resistance. The monitoring record must not become another route for information leakage.
Display routing decisions and hold reasons clearly on the employee's screen. However, a display reading "processed internally" is not itself proof of security. Confirm that actual communications and settings match what is displayed — at deployment and after each change.
Routing destination and approval status are displayed for each request.
When granting exceptions, be specific about scope
Urgent tasks and unusual cases arise in the field. Handling "approved for this time" decisions with only verbal agreement from a user or administrator makes it impossible to confirm later what was permitted. Record the target document, destination, purpose, deadline, and approver, and limit the scope.
Even administrators with elevated permissions are not exempt. Consider whether the person changing settings and the person approving the change can be separated, and whether changes can be verified afterward. In small organisations where roles cannot be fully separated, decide on feasible procedures such as confirmation records and periodic reviews.
Explanations returned to users also benefit from care. Rather than simply displaying "prohibited," showing "switched to on-premises processing because internal materials are included" or "awaiting approver confirmation because classification could not be verified" makes the next action clear. Also confirm that error details do not expose too much confidential information.
In PoC, testing the same question with users of different permission levels makes it easier to find gaps in controls. Confirm that users who can view a document receive an answer with supporting evidence, while users who cannot view it do not receive the content. Check search results, responses, logs, and notifications separately to confirm each stays within the intended scope.
In this way, security and usability are not separate problems. A design that allows progress to the next approved action even when a hold or rejection occurs is what makes it possible to follow rules in practice.
Divide safe usage between the system and operations
Documenting rules alone does not guarantee consistent judgement in the field. Reflect routine restrictions in the system; pass difficult exceptions to a responsible person. Making this division of responsibility clear avoids placing the burden of judgement on individual employees.
For example, prepare test documents that cannot be sent externally, and vary conditions — attachments, long text, images, mid-conversation. Confirm expected behaviour not just in normal operation, but also when the classification function stops, the connection destination changes, or permissions expire.
Information-protection design is not a one-time effort. When models, tasks, or the organisation change, revisit classification and permissions. Next time, we examine the compute platform supporting this protection, generation, and audit processing — starting from an 8-GPU configuration example.
Reference 1: NIST SP 800-207 Zero Trust Architecture — https://nvlpubs.nist.gov/nistpubs/SpecialPublications/NIST.SP.800-207.pdf